Key Takeaways
- Most lists of open-ended questions ignore the only number that matters. Pew Research Center finds open-ended questions on its American Trends Panel draw around 18% item nonresponse against 1% to 2% for closed-ended ones. A question nobody answers produces no insight, however well it reads.
- Cognitive burden predicts nonresponse better than topic does. Pew's low-burden questions sit near 6% nonresponse and high-burden ones near 18%. Grade a question on how hard it is to answer, not on how interesting the answer would be.
- Length of the ask is a lever you control. Prompts requesting multiple sentences run several points higher in nonresponse than prompts asking for a word or a short sentence. Ask smaller and you get more.
- Free text is the riskiest field in any GDPR survey. It is the one place where you cannot predict what personal data a respondent hands you, so retention limits and access controls matter more here than anywhere else on the form.
The useful question here is not which open-ended questions to ask. Hundreds of lists answer that. It is which ones people will type an answer into on a phone, at the end of a survey, when they are already bored. That turns out to be measurable, and the research is unambiguous: skipping is driven by how much mental work an answer takes, not by the subject matter. So the examples below are graded by burden, and the section after them shows how to move a question from one grade to another.
Wording is also only half of survey quality. The other half is who answers: our guide to customer research surveys covers the sampling frame, from keeping bots and duplicate respondents out of the dataset to authenticating who is behind each response.
Why open-ended questions go unanswered
Pew Research Center runs the American Trends Panel and publishes its own item-nonresponse data. In its analysis of why some open-ended questions get skipped more than others, closed-ended questions average 1% to 2% nonresponse. Open-ended questions average roughly 18%, with individual questions ranging from 3% to just over 50%.
That fifty-point spread is the interesting part. It means the format is not the problem. The question design is.
Pew tested several explanations and found cognitive burden the strongest. Low-burden questions had a median nonresponse rate near 6%, medium burden near 12%, high burden near 18%. The clearest illustration: asking people to name their preferred candidate drew 3% nonresponse, because that answer already sits in memory. Asking them to propose solutions to a complex social problem drew 52%, because that answer has to be built from scratch.
Length of the ask matters too. Prompts requesting a single word or short phrase saw median nonresponse near 13%, against 18% for prompts asking for multiple sentences. A follow-up Pew analysis of demographic and contextual factors reproduced the pattern at 12% versus 17% and added two findings worth designing around.
The first is device. Respondents on a tablet or phone skipped at 15%, against 11% on desktop or laptop. If half your audience answers on a phone, you are asking them to compose prose with their thumbs.
The second is who drops out. Respondents reporting no partisan lean skipped at a median 31%, against 13% for people who identified with either party. The generalisable point is not about politics: the least invested people leave the box empty. Your verbatims over-represent enthusiasts and complainers, and under-represent the quiet middle that probably explains your churn.
Device and investment are both properties of the mode, not the question. If you are still deciding between web, phone, panel and intercept, our comparison of market survey methods covers what each one does to the answers before any question is written.
The burden test
Before you ship a question, grade it on three things:
- Retrieval. Does the answer already exist in the respondent's memory, or do they have to build it? "What made you cancel?" is retrieval. "How could we improve retention?" is construction, and it is also not their job.
- Scope. How much are you visibly asking for? A question with a bounded object ("which feature") is lighter than one with an unbounded object ("your experience").
- Thumb cost. Read it as if you are on a train with one hand on a phone. If the honest answer runs three sentences, expect a lot of blanks.
Low burden means one retrieval, one bounded object, one short answer. Aim there for any question you genuinely need data from. High-burden questions are not banned, only expensive: budget one per survey and put it last, so an abandonment there costs you nothing else.
Position changes burden as well. For where the open field belongs on a feedback form, the short answer is one optional box directly after the overall rating, asking the reason for it.
38 open-ended survey question examples by use case
Each question below carries a burden grade from the test above. Low-burden questions are safe to place anywhere. Medium can go mid-survey if the survey is short. High belongs at the end, optional, and only when you have a plan for the answers.
Customer satisfaction and churn
Churn surveys are where burden discipline pays best, because the respondent has already decided to leave and has no incentive to write you an essay.
| Question | Burden |
|---|---|
| What made you decide to cancel? | Low |
| What were you trying to do the last time you got stuck? | Low |
| Which tool are you moving to? | Low |
| What is the one thing we do that you would miss? | Medium |
| What almost stopped you from signing up in the first place? | Medium |
| If you came back in a year, what would have to be different? | High |
The first three point at a specific event the respondent remembers. The last one is worth asking at the end anyway, because the few people who answer it tend to be your most articulate former users.
Product and feature feedback
| Question | Burden |
|---|---|
| Which feature did you use most this month? | Low |
| What did you expect this feature to do that it did not? | Low |
| Where did you get stuck? | Low |
| What are you doing outside our product that you wish you could do inside it? | Medium |
| Describe the last workaround you built to get something done. | Medium |
| What should we build next, and who on your team would use it? | High |
"What did you expect this feature to do that it did not" is the highest-yield question on this list. It converts a vague complaint into a specific mismatch between a mental model and an interface, which is directly actionable.
Onboarding and first-run
Ask these within a day of signup, while the memory is fresh. Retrieval cost climbs steeply after that.
| Question | Burden |
|---|---|
| What were you hoping to set up today? | Low |
| Which step took the longest? | Low |
| What did you have to look up or ask someone about? | Low |
| What nearly made you give up during setup? | Medium |
| What did you assume would work differently? | Medium |
Employee and internal feedback
Internal surveys carry a burden nobody grades for: the fear of being identified. Anonymity claims change response rates on open text more than wording does, so state plainly who reads the raw answers before you ask any of these.
In a small team, wording is the bigger risk than metadata. Our guide on how free-text answers re-identify respondents explains why reporting thresholds exist and how to test a form before you call it anonymous.
| Question | Burden |
|---|---|
| What slowed you down most this week? | Low |
| Which meeting could be an email? | Low |
| What is one thing you would change about how we run projects? | Medium |
| What do you need that you have stopped asking for? | Medium |
| What would make you consider leaving? | High |
| What is something leadership believes that is not true on the ground? | High |
The last two are worth the cost once or twice a year. Do not put them in a weekly pulse survey.
Event, webinar and meeting feedback
| Question | Burden |
|---|---|
| What is the one thing you will do differently after today? | Low |
| Which part would you cut? | Low |
| What question did you leave with? | Low |
| What would have made this worth twice the time? | Medium |
| Who else on your team should have been here, and why? | Medium |
Post-webinar forms have a narrow window. Send within an hour, ask three questions at most, and put the open one first because attention drops fast after the session ends.
Sales discovery and lead qualification
Discovery forms sit in front of a booking, so every extra field costs you conversions. Keep the open questions to one or two and let the qualification logic handle the rest with closed fields.
| Question | Burden |
|---|---|
| What are you using today? | Low |
| What made you start looking now? | Low |
| What would need to be true for this to be a priority this quarter? | Medium |
| Who else is involved in this decision? | Medium |
| Describe the process you are trying to replace. | High |
"What made you start looking now" is the single most useful pre-call question in this set: it surfaces the trigger event, which is what your rep needs and what a dropdown can never capture. If you are building a full call structure around these, the discovery call script and question template covers the live conversation rather than the form.
Post-appointment follow-up
| Question | Burden |
|---|---|
| What did you come in for today? | Low |
| What is still unclear? | Low |
| What would have made booking easier? | Low |
| What nearly stopped you from keeping this appointment? | Medium |
| What should we have asked you before the meeting? | Medium |
That fourth question is underused. Answers to it are the cheapest no-show research available, and they usually name something mundane that a better appointment reminder would have solved.
Several of the items above would measure better as a closed question, not a better-worded open one. If the job is to establish a fact rather than collect a reason, dichotomous survey questions carry less burden and give you a variable you can filter on straight away.
Rewriting a high-burden question
Most bad open-ended questions are good questions asked at the wrong altitude. The fix is mechanical: narrow the object, anchor it to a remembered event, and shrink the visible ask.
Start with a question almost every product team has shipped:
How can we improve your experience with our product?
Three retrievals are buried in there. The respondent has to summarise their entire experience, imagine a better version of it, and then work out which parts of that are your responsibility. Nobody does that on a phone. Now narrow the object:
How could we improve onboarding?
Better, still construction work. Anchor it to something that already happened:
What was the most confusing part of setting up your account?
Now the answer exists in memory and the object is bounded. One more pass to cut the visible ask:
Which setup step confused you?
That version reads as a one-line answer, which is what you want. You traded scope for response rate, and four narrow questions across four surveys beat one broad question every time.
The box itself is part of the ask. Glenn Israel's University of Florida study on answer space size found that enlarging the field produced longer responses covering more distinct themes. Size it to match the answer you asked for, in both directions.
What free text does to your GDPR posture
This is the part the question lists skip, and it is the reason open-ended questions deserve more scrutiny than closed ones rather than less.
Every closed question collects data you chose in advance. An open-ended question collects whatever the respondent decides to type. Ask "what could we have done better?" and some answers will name an employee, describe a health condition, or vent about a colleague. You did not ask for any of it and you are now processing it.
Two consequences follow. The data minimisation principle in Article 5(1)(c) limits you to what is adequate and relevant for your stated purpose, and an unbounded text field makes that a promise you cannot keep by design. And if the text contains health, religious, political, or trade-union information, you have landed in Article 9 special category data without a lawful basis for it.
Four practical mitigations, in order of how much they help:
- Say what not to write, in the field label. "Please do not include names or personal details" reduces the volume of unintended personal data more than any downstream process will.
- Set and state a retention window on verbatims. Coded themes can live for years. Raw text should not.
- Separate who reads raw answers from who reads the summary. Most stakeholders need the themes. Very few need the sentences.
- Know where the text is stored and under whose jurisdiction. A server location in Nuremberg does not settle the question if the provider has a US corporate parent, because that is a question about legal reach rather than geography.
If you are working through the wider picture, meetergo's guide to GDPR-compliant software selection covers the vendor assessment side, and the meetergo data privacy page sets out how meetergo handles this for its own customers.
Five mistakes that cost you responses
- Putting the open question first. It is the heaviest item on the form and abandonment there costs you every answer behind it. Closed questions warm people up; the open one goes last.
- Asking two questions in one. "What did you like, and what would you change?" gets you an answer to whichever half is easier and silence on the other. Split it or drop one.
- Ending with "any other feedback?" It has the worst burden-to-yield ratio of any question in common use: unbounded scope, no retrieval anchor, no signal about what you want. Replace it with one specific question or leave it out.
- Making it required. A forced open field converts a skip into either an abandonment or a period typed into the box. Both are worse than a blank you can count.
- Collecting verbatims with no plan to code them. If nobody has agreed who reads the answers and how themes get tagged, you are asking people to spend effort on data you will not use. Decide the analysis before you ship the question.
The same burden rules hold when free text gets scored instead of coded. Two capped prose questions in an application form, each naming the criterion it feeds, give reviewers more to compare than six open boxes.
Tools that help
Any form builder renders a text field. What separates them for open-ended work is whether the field is conditional, whether it is legible on a phone, and where the answers are stored.
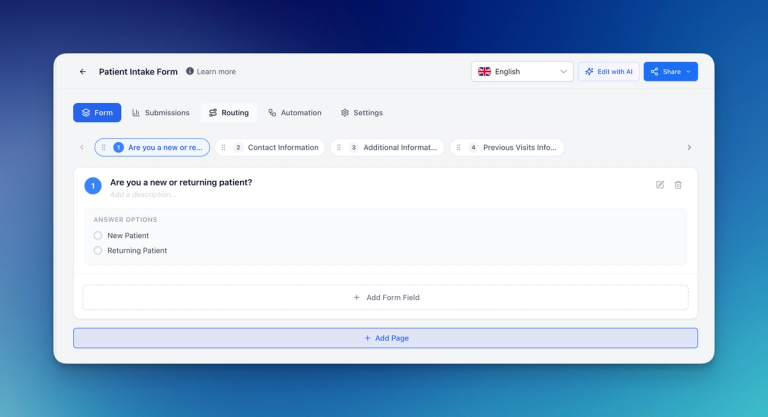
meetergo is a Cologne-built platform covering scheduling, forms, payments, e-signatures and CRM across sales, recruiting, healthcare and other verticals, so its form builder targets forms attached to a booking or a deal rather than academic research. Three things matter for survey work.
Conditional open questions
Branching logic means the open-ended question only appears for the people whose closed-question answer makes it worth asking. Someone who rates onboarding a 9 never sees "what confused you?", which keeps average burden down across the whole respondent pool.
Per-language field labels
Labels can be set per language rather than machine-translated at render time. That matters for open text more than for anything else on a form, because a badly worded prompt in the respondent's second language raises burden invisibly. meetergo's multi-language support covers the booking flow around the form too.
EU-hosted storage with no US corporate parent
Free-text answers stay on European servers under a German company with no US parent, which removes the CLOUD Act question from the assessment rather than mitigating it. That is the jurisdictional point above, applied.
Honest limitation: meetergo does not do verbatim coding. No theme clustering, no sentiment scoring, no auto-tagging of free text. You can export responses into a dedicated analysis tool, but if automated verbatim analysis across thousands of responses is the core of your job, a purpose-built research platform will serve you better.
If you take that export into a language model, keep grouping and concluding as separate jobs. Our walkthrough on clustering open-text answers with AI explains how to check the themes against a random sample of raw answers before you count them.
Also worth knowing: invitee questions attach short questions to a booking without a separate form, routing forms send respondents to different people based on answers, and the free scheduling poll tool handles the narrow case where the only question is which time works.
Build a form that people finish. Set up your first conditional survey on meetergo's free plan, no credit card required.
Booking + video conferencing in one tool.

Booking + video conferencing in one tool.
FAQs
How many open-ended questions should one survey contain?
One or two in a short survey, placed after the closed questions. The constraint is total burden rather than a fixed count: three low-burden questions about remembered events cost you less than one high-burden question asking for recommendations.
Are open-ended questions better than closed-ended ones?
They answer different questions. Closed-ended items tell you how many and how much, at 1% to 2% nonresponse. Open-ended items tell you why, at roughly ten times that rate. Measure with closed questions, explain the measurement with open ones, which is also why the open one goes last.
To see where open questions sit in a full question set, look at how each closed rating is paired with one open follow-up.
What is the difference between an open-ended and a leading question?
An open-ended question sets a topic without supplying an answer. A leading question smuggles one in. "What did you think of our faster checkout?" tells the respondent the checkout is faster, so it is leading even though the field accepts free text. Strip the adjectives and you usually strip the leading.
How do you analyse open-ended survey responses?
Read a sample and let categories emerge from the text rather than fixing them upfront, then tag every response against that codebook so themes can be counted rather than quoted. Keep the codebook small enough that two people applying it independently agree, and report how many responses sit behind each theme.
Do open-ended questions work on mobile?
Less well. Pew found 15% nonresponse on phones and tablets against 11% on desktop and laptop. If most of your traffic is mobile, shorten the prompt, signal that one line is enough, and never mark the field required.
Should open-ended survey questions ever be mandatory?
No. A required free-text field pushes people to abandon the survey or type filler, and both are worse than a skip you can measure. Optional fields also keep your nonresponse rate honest as a signal that the question is too heavy.
Can you ask open-ended questions anonymously?
Yes, and for internal surveys you usually should. State who reads the raw text before the question, keep the response separate from any identifier, and hold the retention window short. Anonymity respondents do not believe produces cautious answers, which is worse than fewer answers.